Post-selection for QML and its Distribution across the Model

This abstract has open access
Problem description and relevance

(pdf file attached Abstract.pdf  for linked sources :)

1 Problem description and relevance

Next to efficiently optimizing a circuit covering an exponentially growing Hilbert space, quantum machine
learning (QML) faces the difficult task of mapping classical data to the quantum computer such that unknown
patterns can be identified with a unitary circuit [13]. Presently, this task is being addressed with research
into encoding schemes [13] and methods based on data-reuploading [13, 4]. However, these methods are not
applicable to quantum data, unless one combines multiple samples, which corresponds to data-reuploading. The
core problem is that separation between two quantum states can not be increased using any quantum channel,
which is known as the quantum data processing inequality [19]. Thus, any encoding that does not sufficiently
separate two classes on the large Hilbert space has limited ability to classify them, especially when partially
tracing to a smaller Hilbert space. The only way to increase the performance is to include non-linear pre-
or post-processing steps, data-reuploading being the most prominent case. With post-selection we propose a
more explainable approach, as compared to other non-linear operations, which directly identifies advantageous
subspaces that offer better separation than the complete Hilbert space.


The use of post-selection in a machine learning context is motivated by the outperformance of classical
tensor networks (CTNs) compared to quantum tensor networks on some problems [10]. Given some non-
linearities in the encoding their optimal linear combination is usually not unitary. The core differences between
CTNs and quantum circuits can be tied to two physical phenomena: First is entanglement, which relates to
the bond dimension [3, 12]; Second is the amount of post-selection, see [11]. Commonly, CTNs reduce the
Hilbert space without partial traces, quantum channels only employ partial traces [9, 18]. In previous work the
authors proposed a hybrid approach between the two models [11], i.e. post-selection can be made trainable.
By controlling a rotations on post-selected ancillas one can implement any diagonal matrix up to a global
scaling factor on a quantum compute, a simple operation that is otherwise inaccessible on quantum computers,
but easily implemented with a CTN. The core idea of implementing classical operations with post-selection is
already known for other quantum algorithms, such as those solving partial differential equations [17, 15].


A big drawback for post-selection are the wasted shots on a quantum computer, which is why it is to be
used sparingly. In this work, we aim to investigate how limited post-selection distributes itself inside a QML
model. Understanding how this resource is distributed in models allows us to understand the structure of the
selected subspace, which can be used as a stepping stone for the design of methods that treat the discarded
subspaces. To this end, we use a hyperparameter from our previous work [11] that controls the amount of overall
permitted post-selection. It controls the normalization of the output after post-selecting and corresponds to
the number of shots kept after the post-selection. Thus, it allocates post-selection to the QML model during
training, improving QML both for classical and quantum data.


Submission ID :
48
Submission Topics
Methodology :

2 Methodology

Let ρi be the density matrix of the encoded data i of the dataset. Following [11], we take the hyperparameter

t that controls post-selection by inserting the normalization
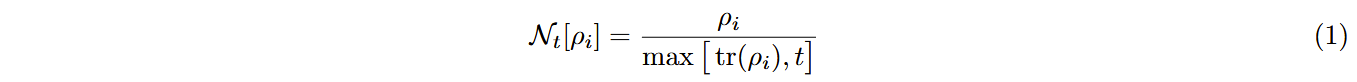
into the loss. To ensure numerical stability of the logarithms in the cross entropy loss, during numerical

experiments we add a depolarizing channel [19, 2]
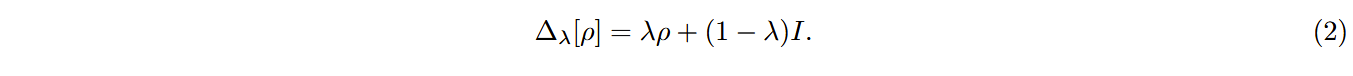
However, λ = 0 simplifies theory development. Thus, the adapted crossed entropy loss Lt [8, 14] for a post-

selected QML model reads
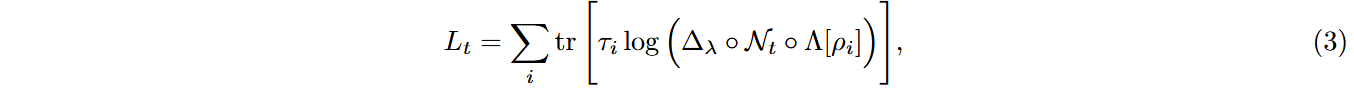
with a completely positive (but not trace-preserving) map Λ. Partial post-selection which is not trace-preserving

is implemented as follows: Arbitrary diagonal matrices 0 ≤ D ≤ I, D ̸ = 0 are realized by controlling the rotation

angle to ancillas that are fully post-selected [11]. Generally, the first diagonal element may be chosen 1. This

procedure is equivalent to placing diagonal matrices on the partially post-selected location. For t = 1 no

post-selection occurs, while for t = 0 no limits are placed on post-selection. While there are other choices for

controlling the amount of normalization and thus post-selection, t is the most practical with its interpretation

as a threshold, see Eq. (1).


Based on our simulation data we observed a trend, which we would like to investigate further. For the lack

of more informal means, we define the hypothesis:


    Hypothesis 1. While partially post-selecting is permitted, qudits are either not post-selected at all or post-

    selected fully, except one state that is limited with the amount of permitted post-selection given by t.


As a metric to investigate the hypothesis we identify all diagonal matrices Dj with their diagonal elements

djk in the model that allow for partial post-selection and taking the number of djk ∈ [0, 1] that are some distance

ε from either 0 or 1. To this end, we take the counting function
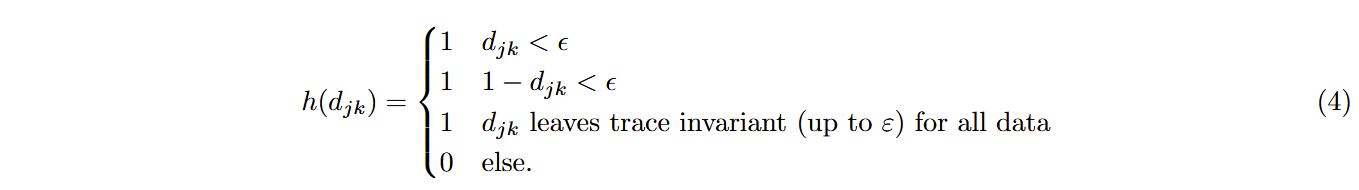
Thus, we obtain the full score s to test Hyp.1 on a trained model
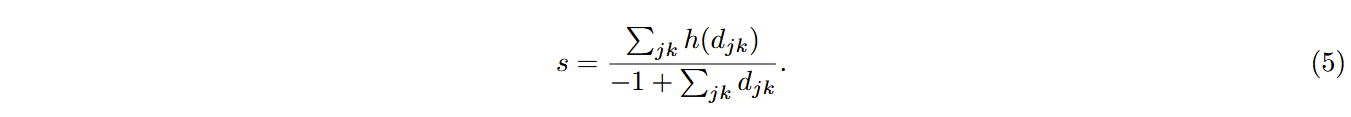
Hyp. 1 is confirmed for scores s ≥ 1.


   When considering diagonal matrices acting on only a subset or individual qubits the diagonal matrices

aggregate to an action on the entire Hilbert space via the tensor product. For instance, the partial post-

selection of one qubit splits the entire Hilbert space in two subspaces that each get multiplied with respective

factors. In this work we focus on the entries of the individual diagonal matrices and not their aggregated action

because those may also be separated by layers of unitary operations or generally other quantum channels.

Multi-qubit diagonal matrices allow for a higher precision, i.e. allow the selection of smaller subspaces.
Practical demonstration :

3 Practical demonstration

We investigate two models for different classification learning tasks. First is a model derived as a quantum
classical hybrid via tensor networks [11]. It is a simple prototype that demonstrated the impact of post-selection
on QML. However, in practical settings it is quite inconvenient as a quantum model because it encompasses
the classical case as well. Thus, the second model will use more established methods with a simple brick wall
ansatz with inserted post-selection layers.

3.1 Tensor Network Model
The tensor network based model building on [16], is motivated by the underlying theoretical arguments [11]
leading up to Eq. (1). The tensor network is displayed in Fig. 1a. It uses rotational encoding of the iris dataset
[5, 1] that is processed by an isometric matrix product state (MPS) with variable bond dimension χ during
training and with trainable reduction operators of dimension ξ. The overall channel corresponds to a completely
positive map and is trace preserving if all reduction operators are chosen to be the identities, i.e. partial traces.
Choosing all reduction operators to be rank 1, i.e. doing post-selection, enables the channel to represent any
unnormallized classical MPS.
The results are obtained by training on the full training data, and a stable initialization obtained from the
data, s.t. the results for each hyperparameter pair χ and t are obtained from a single run. With this approach
we observe overfitting for small t < 0.1, while testing scores and accurarcies significantly improve at t ≈ 0.5.
From the results in Fig. 1b we observe that the hypothesis holds for a sufficiently large threshold t > 10−3.

3.2 Brick Wall Circuit

To complement the theoretically motivated ansatz we probe a quantum circuit more native to QML [13] composed of amplitude encoding and brick wall layers of fully parameterized unitaries separated by inserted trainable partial post-selection operators. It is trained on the first 4 labels of the MNIST1D dataset [7]. The setup is
batch trained with 10-fold cross validation with respective random intializations. Each run is repeated once
with alternative choices of hyperparameters of the ADAM optimizer, resulting in 20 trained setups.

From Figs. (1) and (2) we conclude that generally Hyp. 1 should be rejected and an amended version focusing on larger t should be considered. A possible explanation would be the limited post-selection forcing a more coarse grained use of partial post-selection which presents itself as the distribution in Hyp. 1. Instead of finer weighing of different subspaces, large sections of the Hilbert space are removed. This removed subspace rotates with a deacreasing threshold t, s.t. it has more overlap with the data resulting in a higher use of post-selection but no change in the entries of the operators imposing partial post-selection. Once most of the subspaces with negative classification performance are fully removed, further improvements can be made by careful weighing of the remaining Hilbert space, causing the observed change in entry distribution for t < 0.1 and in Sec. 3.1 for t < 10−3.


Application potential :

4 Application Potential

From the data we observe that the original hypothesis does not generally hold. The observations for the larger
thresholds coinciding with realistic choices do not extend to smaller thresholds, see Figs. 1b and 3b. Furthermore,
individual runs in Fig. 3a seem to violate the hypothesis even for larger thresholds. There, instead of a single
site we have a few sites that do not get counted by the counting function in Eq. (4). Thus, we reject Hyp. 1.
However, we do observe a propensity of the diagonal entries to be mostly concentrated at the edge of the domain,
i.e. either no post-selection or full post-selection is preferred on most sites.


We can identify application potential for post-selection in QML in the following points: Firstly, post-selection
may be applied to improve a QML model or serve as a simple gauge on the further potential of non-linearities
for the model. For quantum data it also offers a way to implement non-linearities without growing the Hilbert
space to account for data-reuploading. Secondly, high potential lies in the explainability. The understanding
that for sufficiently large t trainable partial post-selection leads to a pruning of the Hilbert space instead of a
different weight distribution for the subspaces allows us to develop strategies that target and rectify the pruned
subspace. A possible approach would be to replace post-selection with controlled operations that directly
induce non-linearities, e.g. via data-reuploading, on the removed subspaces. Thus, post-selection might serve
as a building block towards more advanced strategies. Ultimately, an encoding that is successively built up may
be possible, which as a structured approach could address major issues in QML, such as barren plateaus, the
choice of encoding, and the choice of circuit.


To this end, further understanding of the associated theory is needed. There also remain practical concerns
how models with post-selection can be optimally trained, especially with regards to batching the data.


Acknowledgements

G.J received funding from the DLR (German Aerospace Center) through the Quantum Fellowship Program.
Furthermore, the project was enabled by the DLR Quantencomputing-Initiative and the German federal ministry
of Research, Technology and Space; https://qci.dlr.de/projekte/qutenet


Associated Sessions

Research Associate & PhD student
,
DLR e.V. (German Aerospace Center)
Research Associate
,
German Aerospace Center (DLR e.V.)
16 visits